


Kimi K3 is live through Moonshot’s API, kimi.com, Kimi’s mobile apps, Kimi Work, and Kimi Code. OpenRouter also provides immediate access for people who do not have a Moonshot account. The model has 2.8 trillion parameters, native vision, a 1M-token context window, and $3/$15 pricing.
Moonshot describes Kimi K3 as a long-horizon agent model for software engineering, knowledge work, and multimodal reasoning. K3 uses Stable LatentMoE with 896 experts and activates 16 of them. The launch materials include benchmark scores, deployment recommendations, extended agent demonstrations, and three candid limitations.
Independent results arrived quickly. Artificial Analysis gives K3 a score of 57 on its Intelligence Index and ranks it fourth among 189 models. It sits behind Claude Fable 5 and two GPT-5.6 Sol reasoning settings, then ahead of Claude Opus 4.8, GPT-5.5 at xhigh, Claude Sonnet 5, and GLM-5.2.
Today’s release runs on Moonshot’s hosted infrastructure. A separate open-weight launch will open the checkpoint to independent hosts. Moonshot says a later technical report will provide more detail about architecture, training, and evaluation. The launch post documents the main reasoning settings, harness choices, and repeated-run rules. Full prompts, evaluation code, and end-to-end cost accounting remain unpublished.
What Kimi K3 Includes
Moonshot’s Kimi K3 quickstart describes a 2.8T-parameter model built with Kimi Delta Attention and Attention Residuals. K3 accepts text, images, and video, supports a 1,048,576-token context window, and targets software engineering, knowledge work, and deep reasoning.
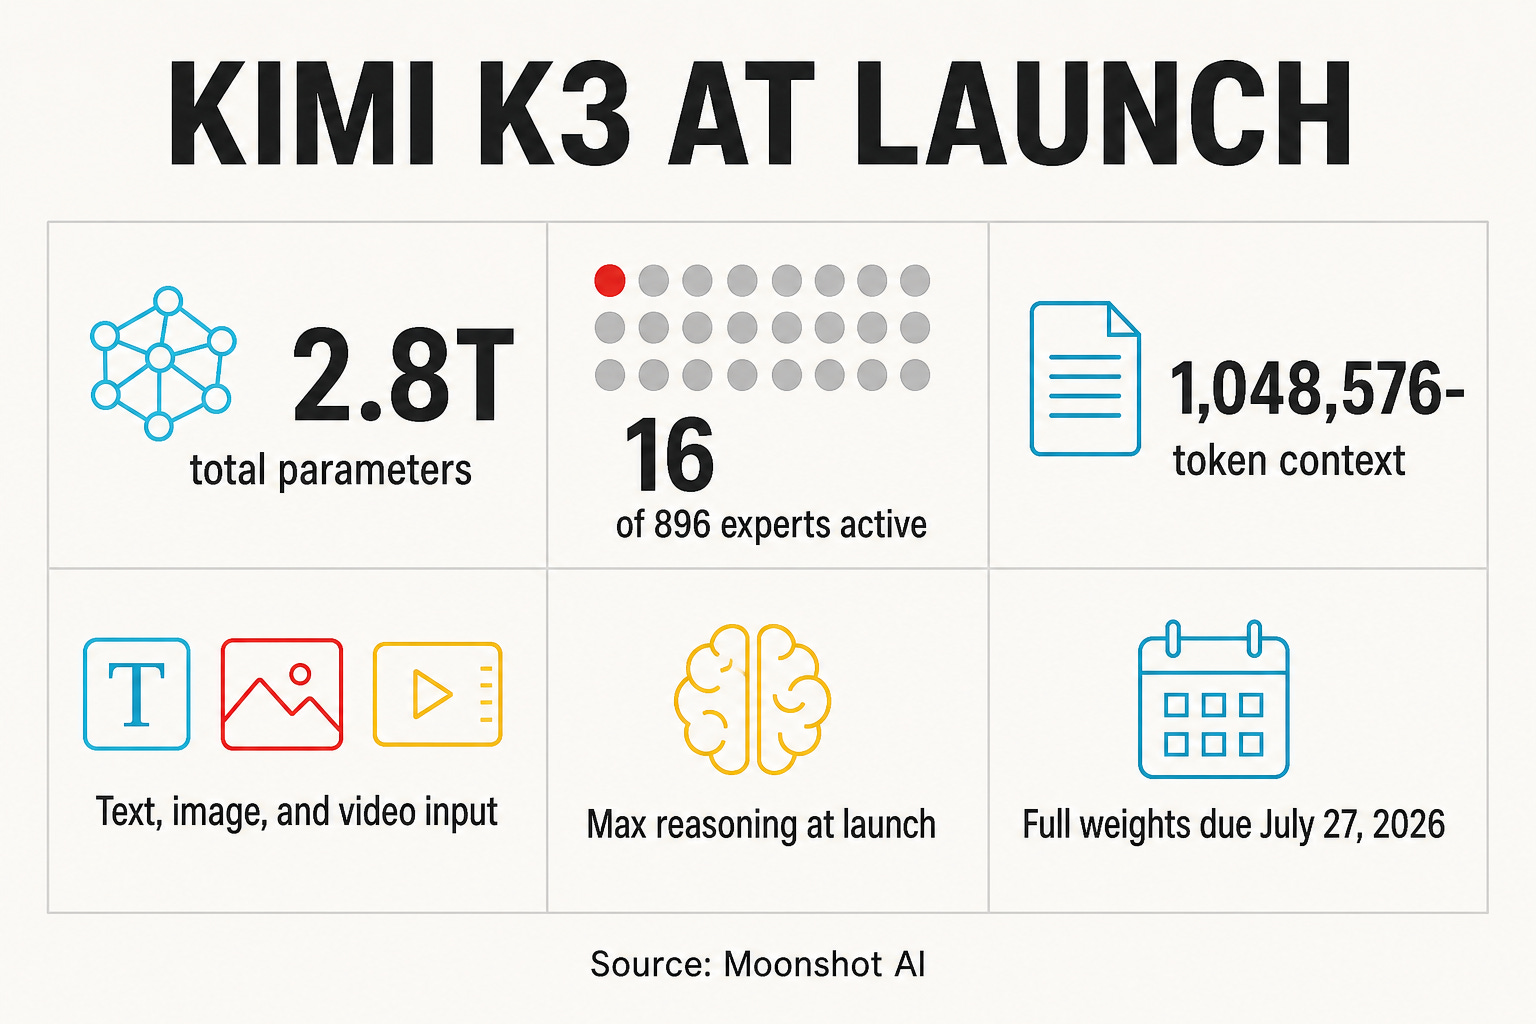
Several launch constraints deserve attention. Sampling values are fixed. K3 currently accepts only maximum reasoning effort. Streaming separates reasoning_content from the final answer. Multi-turn agents must return the complete assistant message to the next request, including the reasoning and tool-call fields the API supplies.
K3 is available through kimi.com, Kimi’s mobile apps, Kimi Work 3.1 or later, Kimi Code, and the API. Moonshot is also preparing Kimi Hosted Agent, an enterprise platform with agent harnesses, isolated sandboxes, and long-running environments.
Kimi K3 Pricing and API Costs
Moonshot prices K3 at $0.30 per million cached input tokens, $3.00 per million fresh input tokens, and $15.00 per million output tokens. The rate stays flat across the 1M-token context window.
The jump from the K2 generation is substantial.
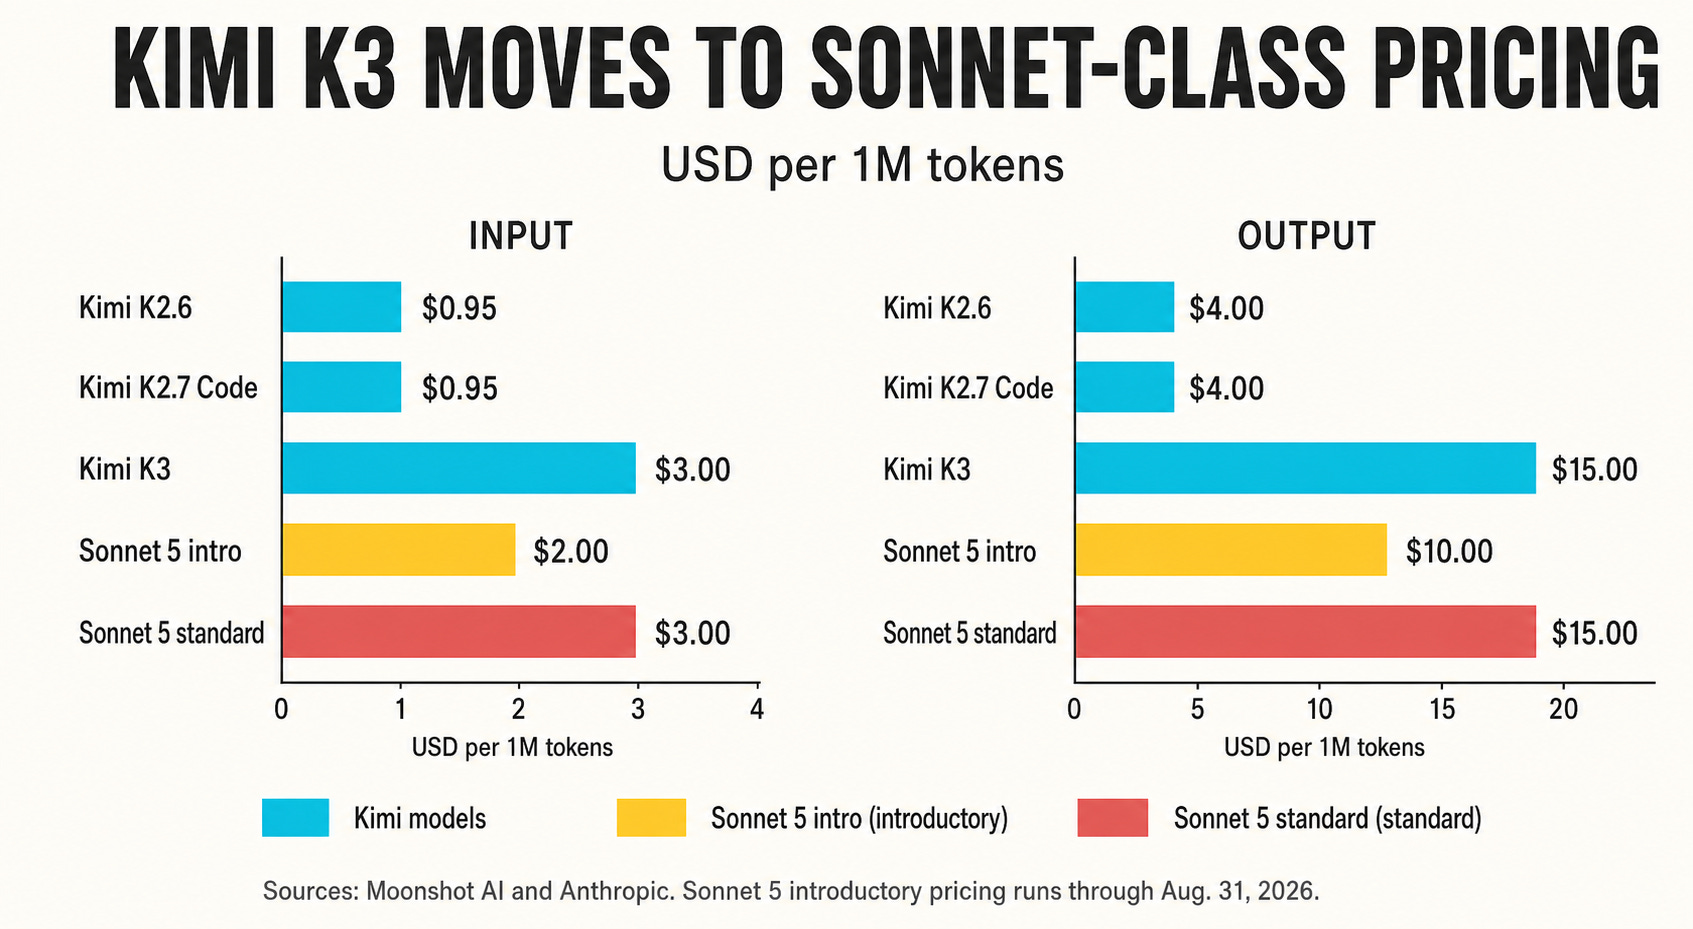
K3 costs about 3.2 times as much for fresh input and 3.75 times as much for output as K2.6 or K2.7 Code. The cached-input increase is gentler, and a K3 cache hit costs one tenth of a fresh input token.
The obvious comparison is Claude Sonnet 5. Anthropic’s standard Sonnet 5 rate is also $3/$15, although introductory pricing of $2/$10 runs through August 31, 2026. K3 therefore matches Sonnet 5’s standard rate and currently costs 50 percent more than Sonnet 5’s launch promotion.
Moonshot is also running a K3 launch top-up rebate through August 12. A qualifying prepaid purchase earns a one-time voucher worth 10 to 30 percent of the top-up. The list price stays fixed, and the top-up is non-refundable.
The Chinese launch post lists the corresponding domestic rates as ¥2 for cached input, ¥20 for fresh input, and ¥100 for output per million tokens. Moonshot says its programming traffic exceeds a 90 percent cache-hit rate through the Mooncake split-inference architecture, reducing effective input cost to roughly one quarter of the uncached rate.
Some of the increase reflects serving cost. K3 has 2.8 trillion total parameters, a 1M-token context window, 896 experts, and a recommended deployment spanning at least 64 accelerators. The remaining premium looks like capability pricing. K3 leaves the low-cost bracket occupied by the K2 generation.
The list price still hides the number that matters for agents. K3 always reasons, and the only launch setting is max. A $15 output rate becomes expensive when a task generates a long reasoning trace, retries failed tool calls, or drags its history through many turns. Automatic caching helps, but it cannot make wasteful reasoning free.
Moonshot makes the same argument in its launch material. Its score-versus-cost charts place K3 on a cheaper task-cost curve than Fable 5 in Kimi Code Bench and GPT-5.6 Sol in BrowseComp. The chart does not yet disclose enough token accounting or harness detail to reproduce those dollar figures.
Artificial Analysis provides a separate cost estimate. Its blended rate assumes a 7:2:1 ratio of cache hits, fresh input, and output, producing an effective price of $2.31 per million tokens. K3 cost about $0.94 per weighted Intelligence Index task, compared with $1.04 for GPT-5.6 Sol at max and $2.75 for Fable 5 with fallback. GLM-5.2 cost about $0.47 per task. The full K3 evaluation cost $2,690.80.
Token use explains part of that bill. Artificial Analysis reports 130 million K3 output tokens across the Intelligence Index, more than twice the 63 million median among comparable reasoning models. K3 can still cost less per task than the two models above it, but its verbosity weakens the savings implied by the rate card.
The right comparison is cost per completed task. K3 has to finish enough work, with enough tool discipline, to justify a rate card that sits beside Sonnet.
Kimi K3 Benchmarks and Model Card Status
Artificial Analysis supplies the first broad independent result.
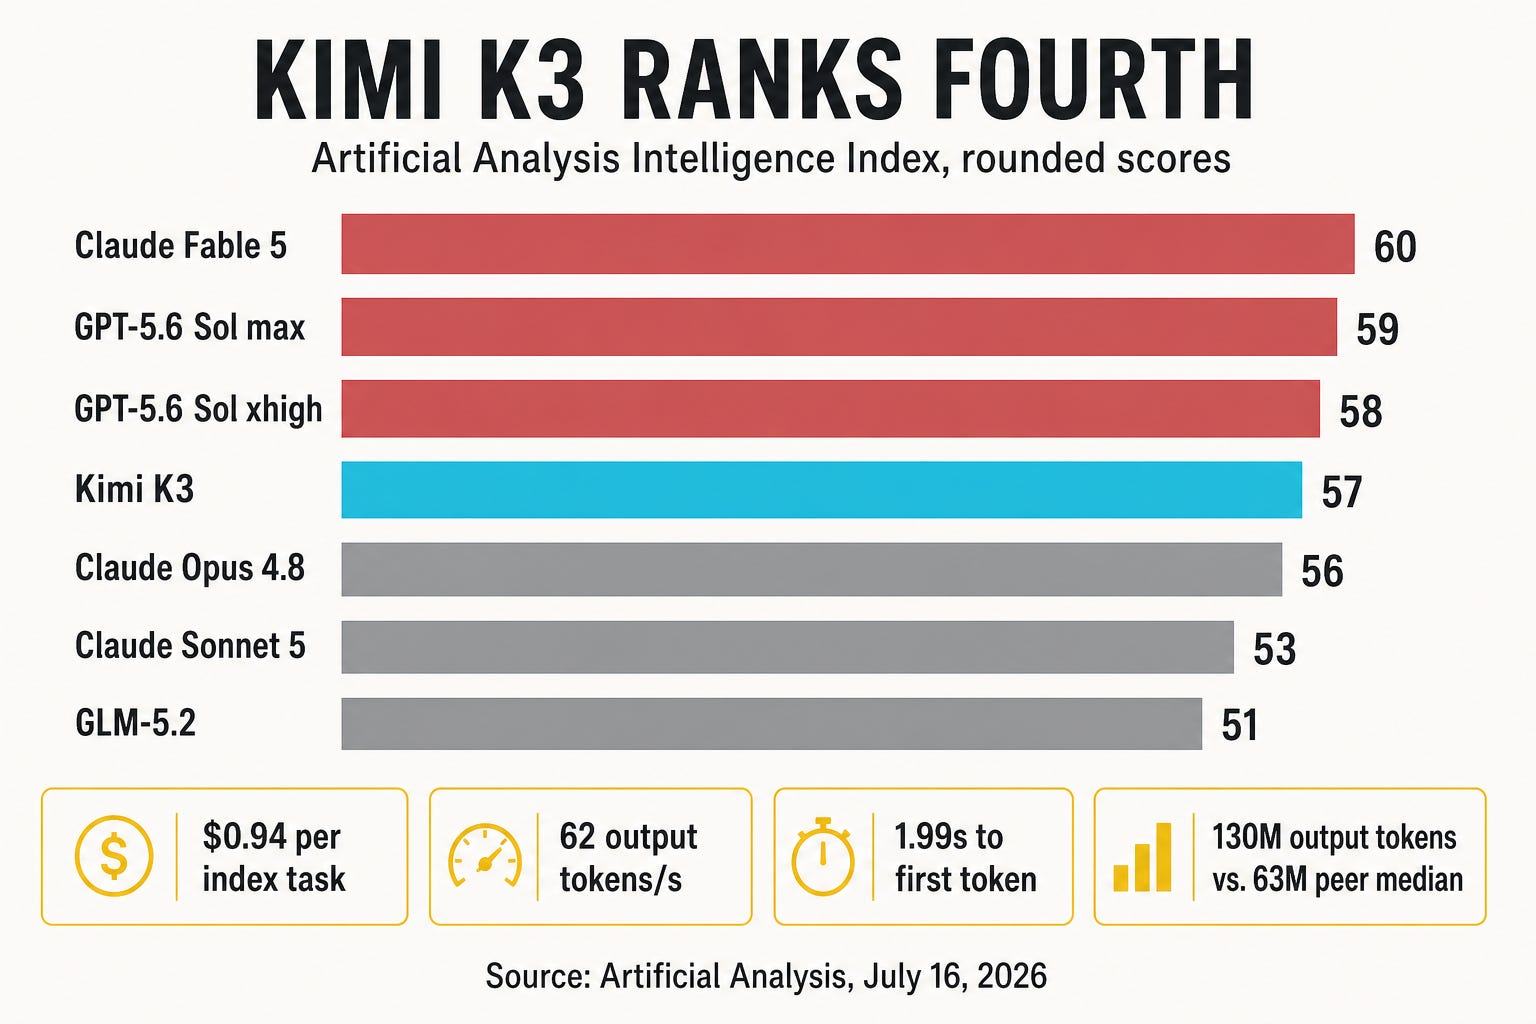
K3 scores 57.1 on the Intelligence Index, placing fourth among 189 models. Artificial Analysis measured 62 output tokens per second and 1.99 seconds to first token through Moonshot’s API. Its weighted estimate puts K3 at $0.94 per index task, below GPT-5.6 Sol at max and Fable 5 with fallback, though K3 generated about twice the peer median in output tokens.
The Intelligence Index v4.1 combines nine evaluations spanning coding, terminal work, banking agents, scientific reasoning, long-context retrieval, and general knowledge. That methodology differs from Moonshot’s launch suite, which explains why the independent ranking is more useful than a row-by-row attempt to match the two tables.
Moonshot now says K3’s overall user experience remains behind Claude Fable 5 and GPT-5.6 Sol, while its evaluation suite puts K3 ahead of every other comparison model. The published charts support that summary, though individual benchmarks move K3 above GPT-5.6 Sol and Fable 5 in several categories.
A full model card and technical report remain pending. The tech blog’s footnotes provide useful evaluation detail. All K3 scores use max reasoning, temperature=1.0, and top_p=1.0. Depending on the benchmark, models run through KimiCode, Claude Code, Codex, Terminus 2, or a benchmark-specific harness.
That mixed-harness design limits direct model-to-model conclusions. Terminal Bench reports the best available harness for each comparison model. FrontierSWE combines Moonshot runs with leaderboard results. Kimi Code Bench uses KimiCode and Claude Code for K3, Claude Code for the Claude and GLM models, and Codex for GPT. Moonshot’s PostTrain runs for K3, Fable 5, and GPT-5.6 Sol average three attempts. Fable 5 requests rejected under its usage policy fall back to Opus 4.8.
DeepSWE provides a useful sensitivity check. K3 scores 67.5 with KimiCode and 67.3 with the benchmark’s mini-SWE-agent harness. That small difference is reassuring for this task, though it does not remove the broader harness issue.

Moonshot reports narrow K3 wins on Program Bench, SWE Marathon, Automation Bench, BrowseComp, SpreadsheetBench 2, DeepSearchQA, and OmniDocBench. The model also finishes within half a point of GPT-5.6 Sol on Terminal Bench and within 0.5 points of Fable 5 on MCP Atlas. FrontierSWE is a clearer loss: K3 scores 81.2 against Fable 5 at 86.6.
The gaps are often small. K3 trails GPT-5.6 Sol by 0.5 on Terminal Bench and leads it by 0.2 on Program Bench. It leads Fable 5 by 0.1 on SpreadsheetBench 2, then trails by 4.6 on FrontierSWE. Those margins make methodology, retry policy, tool setup, and repeated runs important.
BrowseComp exposes another evaluation choice. The reported 91.2 score uses context compaction at 300K tokens, following the Claude model-card strategy. K3 scores 90.4 when it uses the full 1M-token window without context management. The result suggests that a larger context window does not automatically beat selective compaction.
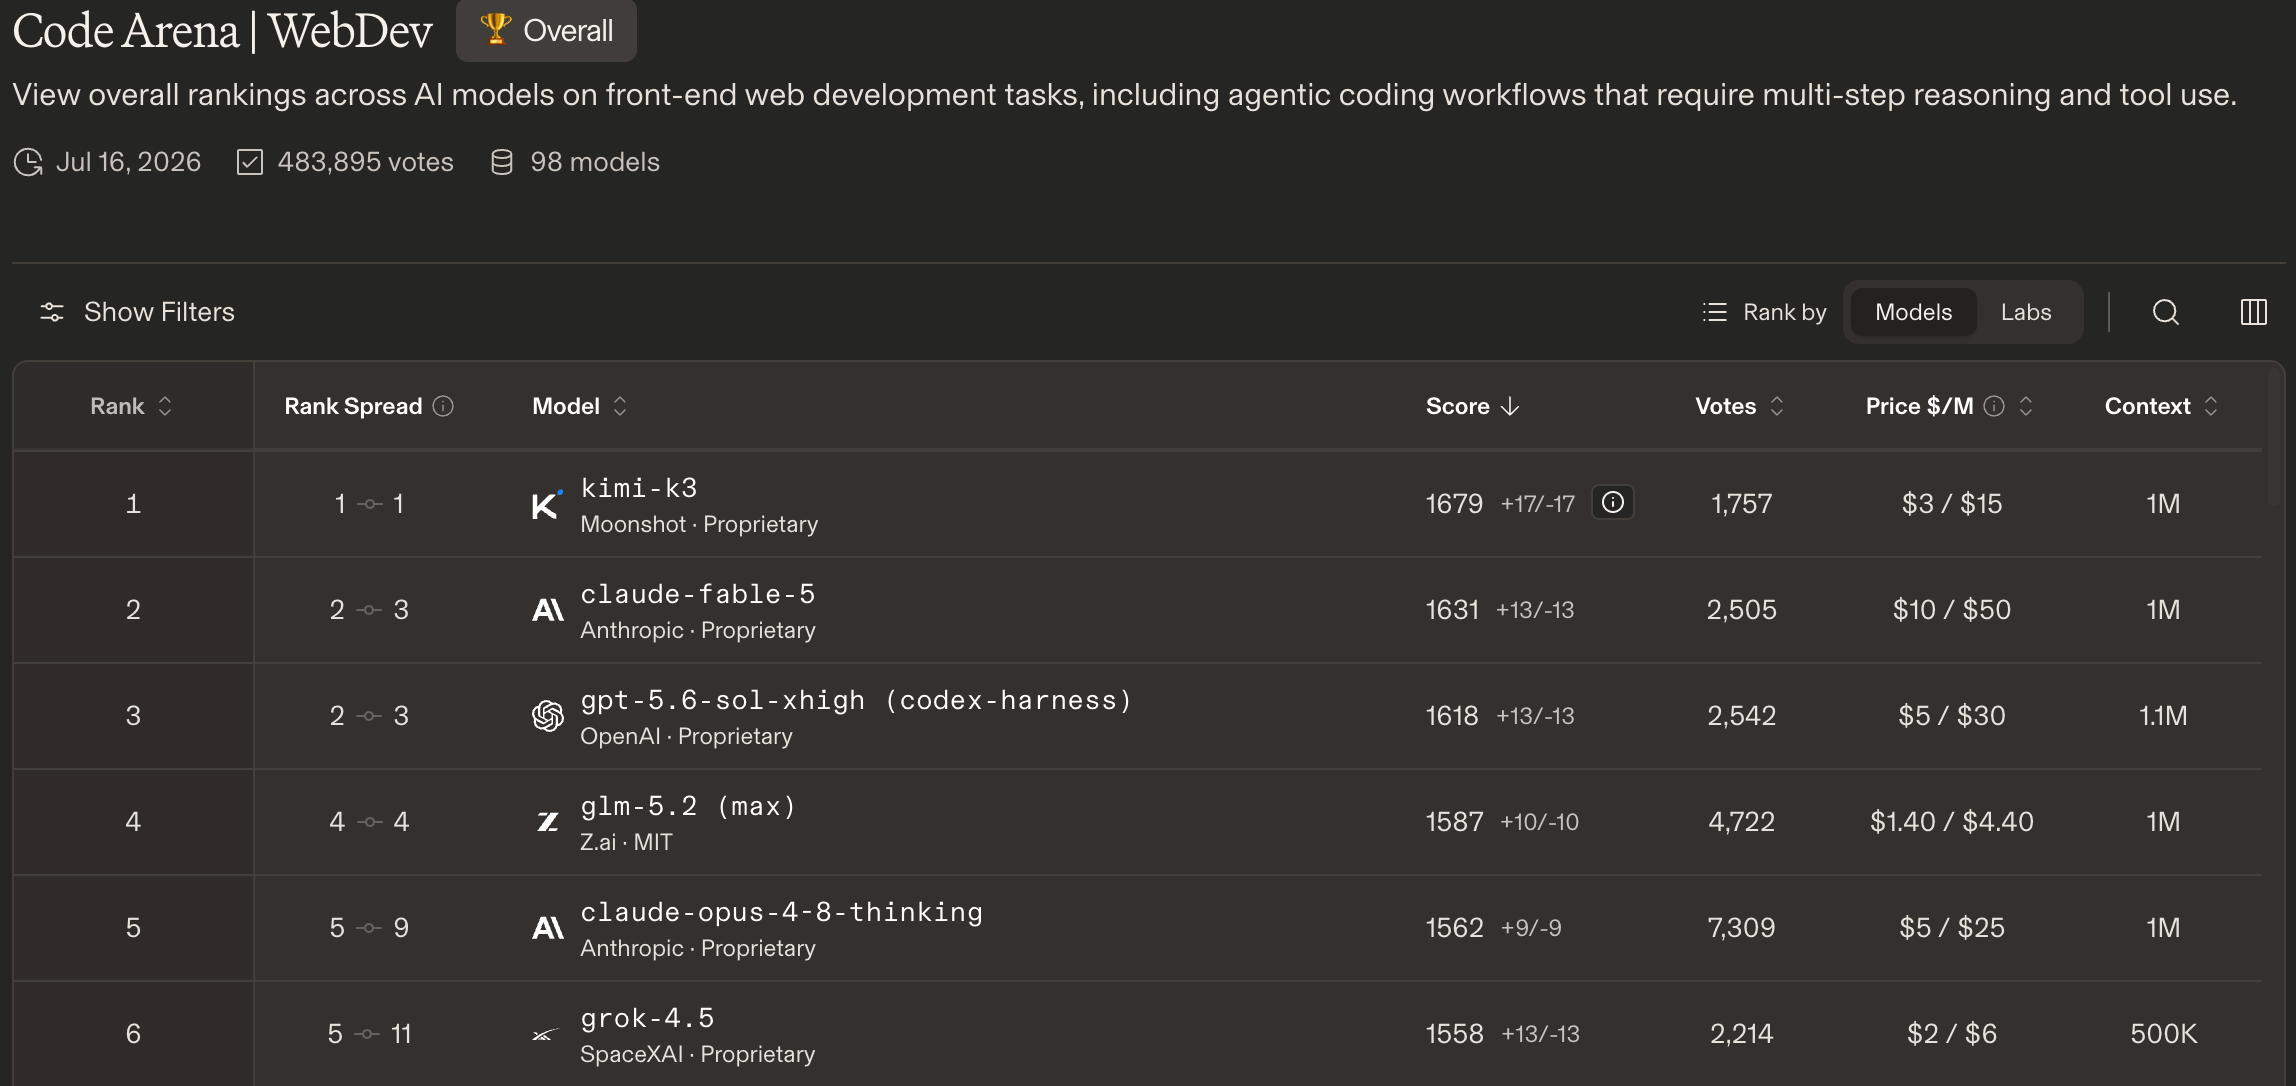
Kimi K3 currently ranks #1 for “Code - WebDev” on arena.ai.
Moonshot’s long-horizon demonstrations are more unusual than the benchmark table. In a 24-hour kernel arena, K3 rewrote and tested GPU kernels across NVIDIA H200 and alternative-vendor hardware. On the Attention Residuals task, the published trace ended at a 59.7 percent speedup over the baseline, compared with 57.1 percent for Fable 5. Moonshot notes that Fable 5 was evaluated by a third party and may include fallback behavior.
K3 also built MiniTriton, a compact compiler with its own tile-level intermediate representation over MLIR, optimization passes, and PTX generation. Moonshot reports performance matching or beating Triton on some supported roofline workloads, plus stable nanoGPT training through the resulting stack. A separate 48-hour agent run designed and verified a 4 mm² chip with 1.46 million standard cells, 0.277 MB of SRAM, an INT4 MAC array, timing closure at 100 MHz, and simulated decoding above 8,700 tokens per second.
The knowledge-work examples are similarly large. Moonshot says K3 reproduced the I-Love-Q relation in computational astrophysics in about two hours after cross-checking more than 20 papers, evaluating more than 300 equations of state, and writing more than 3,000 lines of Python. An ASIC-industry report used more than 120 recursive improvement rounds, 2,800 web searches and crawls, 1,100 terminal data pulls, 87 quarterly reports, and 99 PDFs totaling more than 11,000 pages.
Custom Kimi K3 Performance Benchmarking
I used StackPerf to compare K3 through OpenRouter and Moonshot’s first-party Kimi Code endpoint. StackPerf measures model, provider, harness, and configuration performance. It was the first project built with OpenSymphony, an orchestration platform for long-running agentic work.
The benchmark sent the same prompt sequentially through each route: write exactly 200 words about the cost of long-context inference, using maximum reasoning and a 4,096-token output ceiling.
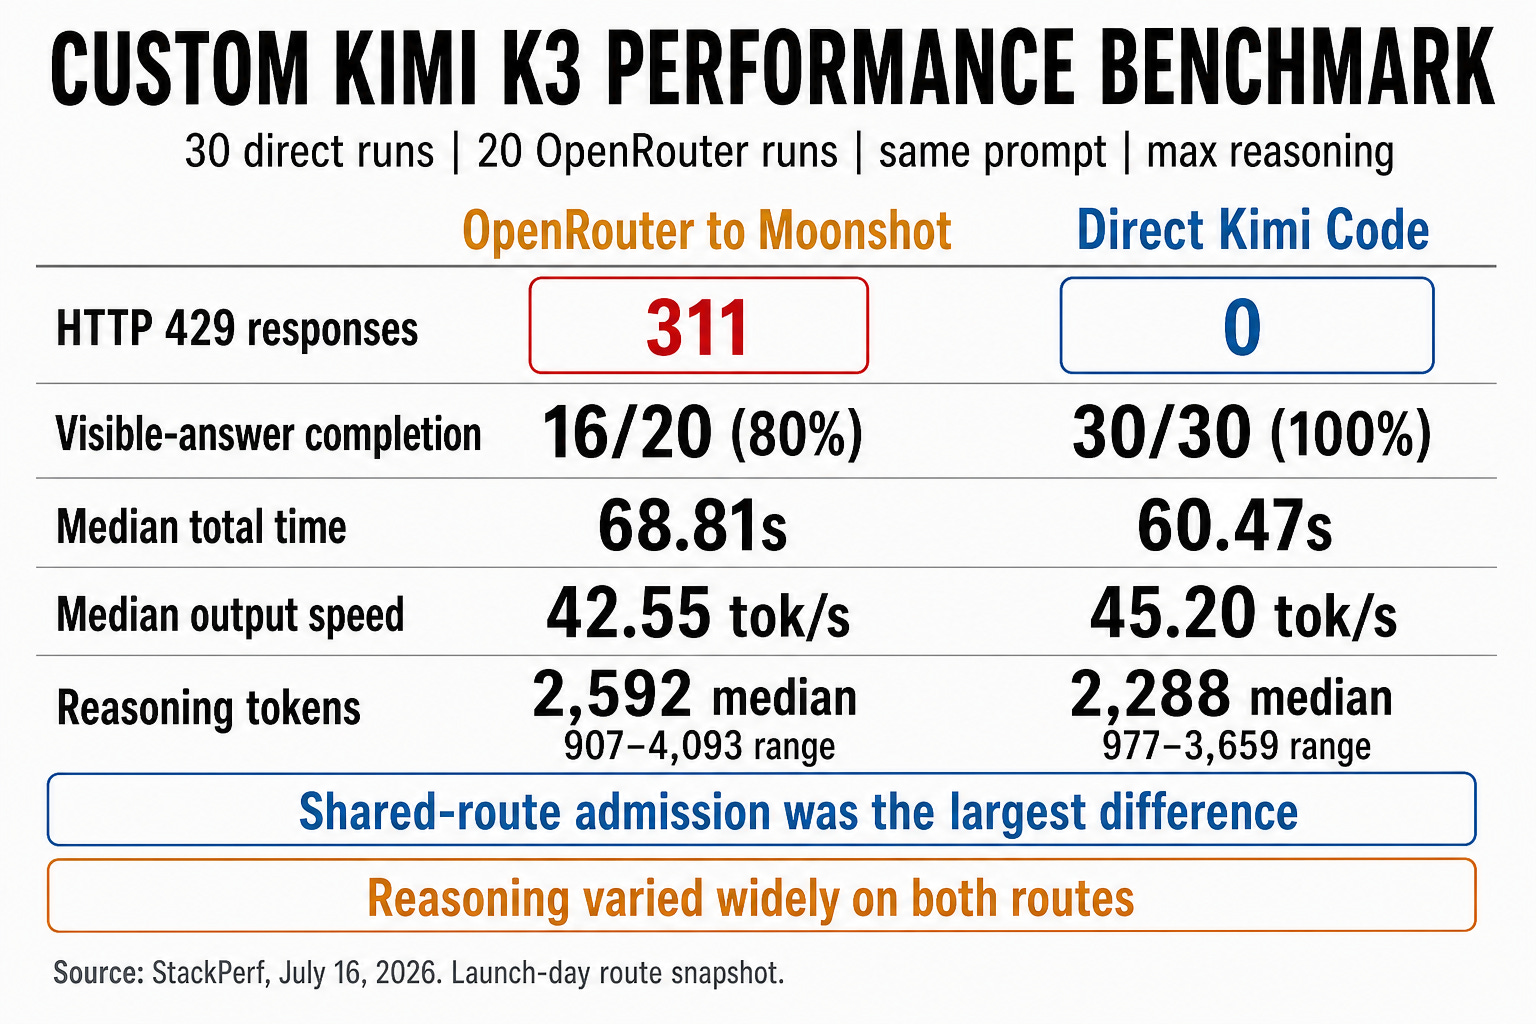
Across identical prompts, reasoning-token use varied by 275% through Kimi Code and 351% through OpenRouter, measured from each route’s lowest run to its highest. Total time varied by 198% and 242%, respectively, while calculated request cost varied by 216% and 253%.
Availability produced the clearest difference. Kimi Code completed all 30 sequential requests without an HTTP error. OpenRouter returned 311 upstream HTTP 429 responses under its one-second retry instruction while collecting 20 measured completions, and 19 of those 20 completion windows required at least one admission retry.
Four requests spent 4,093 of the available 4,096 completion tokens on reasoning, hit the output ceiling, and returned no visible answer. K3 reasons on every request and currently exposes only max reasoning, which means the completion-token budget must cover the reasoning trace and the visible answer.
How to Try Kimi K3 Today
OpenRouter’s Kimi K3 page is the simplest access path for people who already use its API, playground, or model routers. The model ID is moonshotai/kimi-k3; the ~moonshotai/kimi-latest alias also points to K3. OpenRouter exposes the full 1M-token context, text and image input, tool calls, structured outputs, and maximum reasoning effort at Moonshot’s $3/$15 rates.
OpenRouter currently routes K3 requests to Moonshot AI’s hosted INT4 endpoint. It provides a common account, API, and billing layer rather than independent inference. That distinction will matter once public weights let other providers join the route.
Moonshot’s standard OpenAI-compatible API uses the kimi-k3 model ID. Kimi Code subscribers can use k3 through the separate Kimi Code API endpoint.
Moonshot’s tool-calling guide covers JSON Schema function definitions and the assistant-tool-assistant loop. K3 supports tool_choice=”required” when the application needs to force a tool call on the first turn.
The K3 tool-calling best-practices guide also recommends dynamic tool loading for large catalogs. Instead of sending hundreds of tool definitions on every request, the application exposes a small search_tools function, retrieves a relevant subset, then injects full definitions through a system message when needed.
Kimi K3’s Launch-Day Limitations
Moonshot lists three limitations in the announcement.
First, K3 is sensitive to missing thinking history. Its post-training retained prior reasoning across turns, so an agent harness must send the complete historical assistant messages back to the model. Switching an active session from another model to K3 can introduce context interference and unstable output. Moonshot recommends a compatibility-tested harness such as Kimi Code.
Second, K3 can be overly proactive. Training for difficult long-running tasks makes the model more likely to resolve ambiguity on the user’s behalf. Applications that need strict approval boundaries should state them in the system prompt or AGENTS.md, especially before file deletion, deployment, purchases, or external communication.
Third, Moonshot says K3 still trails Fable 5 and GPT-5.6 Sol in overall user experience. That qualification matters because the benchmark charts contain several first-place K3 results. Strong task scores do not guarantee the same stability, judgment, or interaction quality across a long session.
Kimi Delta Attention and Attention Residuals
K3’s 1M-token context relies on architectural changes that reduce memory use and make information flow more selective.
Kimi Delta Attention uses lower-cost linear attention for much of the model, with periodic full-attention layers. In Moonshot’s smaller Kimi Linear research model, it cut KV-cache use by up to 75 percent and decoded up to six times faster than the comparison system at 1M context. K3-specific results await the technical report.
Gated Multi-Head Latent Attention, or Gated MLA, compresses the key/value state stored for earlier tokens and uses learned gates to control how strongly attention heads contribute. Attention Residuals works across layers, letting each layer select useful earlier representations instead of carrying them forward through a fixed residual path.
K3 also uses a mixture-of-experts design. Each token activates 16 experts from a pool of 896, reducing the compute used relative to the model’s 2.8T total parameters. Moonshot reports about 2.5 times K2’s scaling efficiency, though the full report has not yet defined that measure.
Kimi K3’s Open-Weight Launch
Moonshot set July 27 for releasing K3’s full weights in an official company WeChat announcement. Until the checkpoint appears, K3 remains a hosted model and Artificial Analysis classifies it as proprietary.
Fireworks is an expected early host. Its Kimi partner page says it supported K2.5, K2.6, and K2.7 at launch and plans day-zero support for future Kimi releases. K3 will be harder to serve than K2.7 because it has 2.8T parameters, 1M context, and a recommended deployment of at least 64 accelerators.
Artificial Analysis measured Moonshot’s endpoint at 62 output tokens per second and 1.99 seconds to first token. That gives independent hosts a speed baseline. Their services can also be compared on full-context support, cache pricing, reliability, and tool behavior.
Kimi K3 and the New Price of Open Models
Kimi K3 carries open models into Sonnet-class pricing. Its value will be measured in cost per completed task, including reasoning overhead and route reliability. The open-weight release will show what independent serving changes.